The Short Answer
DeepEdu-v1 proposes an on-prem AI tutoring system for Vietnam that reduces hallucinations by combining efficient long-context inference with curriculum-grounded, agentic updates in a two-part SCALE design. This directly targets the trust gap caused by confident but incorrect answers on local material.
Practically, this means schools can keep student interactions local while staying responsive during multi-turn tutoring sessions that stress long-context computation and memory. The agentic layer lets the system update without costly full model retraining.
The approach is a deployment-focused recipe: it addresses data-sovereignty and hardware/latency constraints, but successful results still depend on wiring in verified, SGK-specific grounding and managing long-context workloads effectively.
On this page
- Introduction: Vietnamese on-prem tutoring needs more than a chatbot
- Why This Matters Now: Vietnamese AI tutoring is hitting the “trust + hardware” wall
- How DeepEdu-v1 avoids two common failure modes (latency and hallucinations)
- What SCALE actually is: efficient long-context inference + an evolving curriculum playbook
- Similarity Chunk Rolling (SCR): making million-token tutoring feasible on limited GPUs
- The agentic “playbook” layer: self-improvement without weight updates
- What the experiments show when SCR + playbook learning work together
- Key Takeaways
- Key Takeaways
DeepEdu-v1: On-Prem AI Tutors for Vietnam That Don’t Hallucinate
Introduction: Vietnamese on-prem tutoring needs more than a chatbot
If you’ve ever tried using a general AI assistant for schoolwork, you’ve probably felt the problem: it can sound confident while being wrong—especially when the content is local, like Vietnam’s curriculum (SGK). That’s exactly the gap a new research effort is trying to close. The work is based on new research from the paper DeepEdu-v1: Efficient and Scalable Agentic LLMs for Vietnamese Education (arXiv:2609.31568).
DeepEdu-v1 is about building LLM-powered tutoring that can run on-premise in Vietnam, while staying aligned with local textbooks and reducing hallucinations. The researchers argue that the two obvious paths fail for two different reasons: cloud assistants don’t fit data sovereignty rules, and open models—if naively self-hosted—run into both hardware limits (long-context memory/latency) and local curriculum grounding issues.
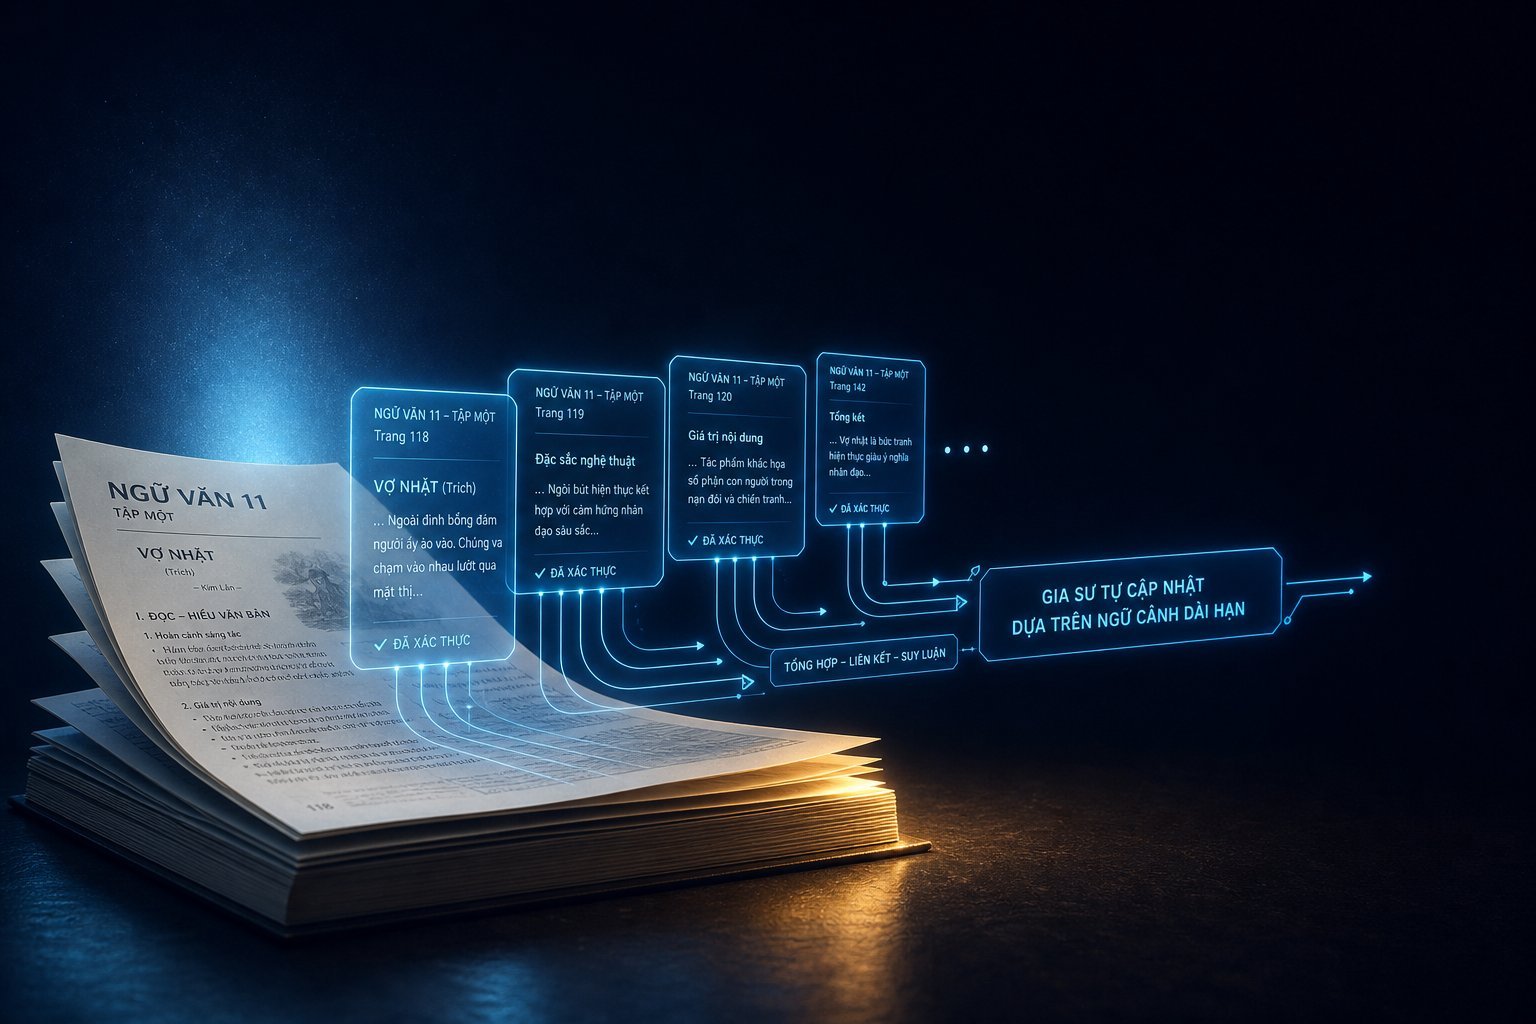
So their answer is a two-part system called SCALE (Self-improving Context-Aware Learning Engine), which combines (1) an efficient long-context inference engine and (2) an agentic “playbook” layer that updates without expensive model retraining. The result is a practical recipe for Vietnamese education: keep data on local servers, stay fast even with long tutoring contexts, and ground the agent in verified, curriculum-specific knowledge.
Why This Matters Now: Vietnamese AI tutoring is hitting the “trust + hardware” wall
This research is significant right now because schools and edtech orgs are moving from “AI demo” to “AI deployment,” and that’s where the constraints get brutal:
- Trust is non-negotiable. When a tutor talks confidently about history, definitions, or curriculum mappings, errors aren’t just “misinformation”—they can become learning data for students.
- Data sovereignty is real. Educational records involve sensitive personal information, and Vietnam’s rules (like Decree 53) push institutions toward on-premise systems rather than sending student data to foreign cloud APIs.
- Hardware is limited. Many schools can’t afford big inference clusters. So even if you can run an open LLM, long tutoring sessions quickly become too slow or even crash due to memory issues.
A scenario where this could apply today: imagine a Vietnamese school deploying an on-prem tutoring system for exam-style problems and textbook-linked explanations. The system would need to:
1) keep student interactions local,
2) retrieve the right SGK-related guidance during tutoring, and
3) remain responsive over multi-turn sessions (where the “context window” grows).
Where previous AI research helped—but didn’t fully solve this—DeepEdu-v1 takes a more deployment-minded stance. Earlier work often focused on model capability or general long-context tricks. This paper instead targets the intersection of three things that deployment teams actually care about: on-prem compute efficiency, localized grounding, and safe “self-improvement” without retraining the model weights. The key idea is: build the system so it’s fast enough and trustworthy enough to be used repeatedly by students.
How DeepEdu-v1 avoids two common failure modes (latency and hallucinations)
The paper starts by dissecting why generic tutoring approaches fail in Vietnam:
1) Why cloud tutoring is a non-starter
Cloud assistants (like ChatGPT-style services) often route sensitive student data to remote servers. That collides with Vietnam’s data-localization expectations (the paper cites Vietnam’s Decree 53). So the system must be self-hosted on-premise.
2) Why “just self-host an open model” still fails
Even if you run an open LLM locally, you still get:
- Long-context bottlenecks: tutoring sessions can reach extremely long contexts, stressing KV cache memory and prefill latency. That’s where out-of-memory (OOM) errors and slow responses become common on consumer or modest GPUs.
- Curriculum misalignment: most pretrained models are shaped by Western-leaning corpora. Their knowledge of Vietnamese SGK material can be incomplete or inconsistent, which increases hallucination risk.
The paper even points to real deployment examples where ungrounded models produced severe history hallucinations in Vietnam (e.g., confusing real-world institutions and historical identities). The takeaway: a tutoring system needs verified grounding, not just fluent text.
What SCALE actually is: efficient long-context inference + an evolving curriculum playbook
DeepEdu-v1’s core is SCALE, which combines two major components:
- Similarity Chunk Rolling (SCR): makes long-context inference efficient by reducing expensive retrieval calls during the prefill stage.
- Agentic Context Engineering-style playbook updates: keeps the model grounded using a structured, auditable “playbook” that evolves from feedback—without updating model weights.
Here’s the comparison the paper implies across approaches:
| Approach | Grounding in Vietnamese curriculum | On-prem deployment fit | Long-context efficiency |
|---|---|---|---|
| Cloud chatbot | Low to inconsistent | ❌ (data leaves local control) | Varies, but not designed for on-prem constraints |
| Self-host generic open LLM | Often inconsistent (hallucinations) | ✅ | ❌ KV cache + prefill can blow up |
Quantization only (e.g., AWQ, GPTQ) |
Doesn’t fix hallucinations | ✅ | Improves weights, not KV cache/latency |
Selective sparse attention only (e.g., TokenSelect) |
Doesn’t fix grounding | ✅ | ✅ helps latency, ❌ no self-improving curriculum |
| Agentic context engineering only (playbook ideas) | ✅ improves grounding | ✅ | ❌ may still be too slow for million-token contexts |
DeepEdu-v1’s novelty is that it couples the efficient long-context engine with the curriculum-grounded self-improvement layer.
You can read more technical details in the original paper here: DeepEdu-v1 on arXiv.
Similarity Chunk Rolling (SCR): making million-token tutoring feasible on limited GPUs
To understand SCR without drowning in math, think of it like this:
When a tutoring session gets long, the model has to “look back” at an enormous amount of prior context. SCR’s goal is to avoid repeatedly re-searching the same relevant parts.
The bottleneck: selective sparse attention wastes retrieval work
The paper builds on selective sparse attention, where the model doesn’t attend to all cached tokens. Instead, it:
1) selects a small subset of “important” KV cache entries using a query-aware retrieval step, then
2) attends only to those selected entries.
But a key inefficiency remains: during chunked prefill, the selection step happens for every sub-chunk. If neighboring sub-chunks are similar (common in real text), then their “important tokens” overlap heavily—meaning you’re doing a lot of redundant retrieval.
SCR’s key move: roll similar sub-chunks into clusters
SCR introduces cluster-level selection:
- The prefill input is divided into outer chunks, then into sub-chunks.
- SCR measures similarity between consecutive sub-chunks (using mean-pooled query representations).
- It forms clusters of similar sub-chunks and runs the expensive selection step once per cluster instead of once per sub-chunk.
To prevent drift (where the cluster anchor slowly becomes unrepresentative), SCR uses an anchor-based clustering rule: members must remain similar to the cluster’s starting sub-chunk anchor, not just their immediate neighbors.
The measurable result: ~35% lower prefill latency and big retrieval-call reduction
In experiments on long-context benchmarks, SCR shows strong reductions in time-to-first-token (TTFT). The paper reports that with settings θ=0.95 and Lmax=4096:
- TTFT latency drops by roughly 35% on average
- Example task numbers:
R.KV: from13.2sto8.3sCode.D: from8.8sto5.7sMath.F: from8.7sto5.7s
And the big structural reason: SCR issues 7.7× fewer retrieval calls during prefill—close to the theoretical 8× bound—because it compresses repeated sub-chunk selection into cluster-level selection.
Accuracy isn’t sacrificed (and sometimes improves)
This is crucial: it’s easy to build systems that are faster but worse. SCR instead keeps accuracy very strong:
- On
InfiniteBench, SCR matches or exceeds theTokenSelectbaseline on nearly all tasks. - A standout improvement:
R.KVjumps dramatically:- with larger cluster sizes,
R.KVreaches 98.0% vs baseline 91.0%
- with larger cluster sizes,
- On
RULER(needle-in-a-haystack retrieval tasks), SCR stays competitive at every context length, with a small improvement at the longest tested context:- 65.28% vs 64.78% at
128Ktokens
- 65.28% vs 64.78% at
A nice practical implication: SCR doesn’t just make long tutoring “possible”—it makes structured retrieval tasks (which map well to tutoring and curriculum grounding) more reliable.
The agentic “playbook” layer: self-improvement without weight updates
Speed is only half the story. A tutor must also be correct about curriculum-specific content.
DeepEdu-v1 uses a playbook-based approach inspired by Agentic Context Engineering (ACE). The philosophy is simple:
- Don’t keep hammering the model weights (expensive and can cause forgetting).
- Instead, maintain a structured, auditable playbook of tutoring rules, explanations, and common failure analyses.
- After interactions, update the playbook using feedback—while leaving the backbone LLM frozen.
Roles: Generator, Reflector, Curator
The system splits responsibilities:
- Generator: produces a tutoring response and reasoning trajectory using relevant playbook content.
- Reflector: checks what happened against reference feedback (answers, graders, deterministic environment outcomes, or teacher corrections).
- Curator: converts Reflector insights into small typed edits to the playbook (add/update/merge/delete operations), with validation safeguards so malformed edits don’t corrupt the knowledge base.
This is a big difference from “prompt stuffing” or free-form self-editing. Because the playbook is structured and entry-based, it can be inspected, audited, and fixed.
Retrieval-Augmented Execution (RAE): only load what matters
As the playbook grows, passing everything becomes slow and noisy. So DeepEdu-v1 adds RAE, which retrieves only the most relevant bullets before generation.
The paper’s experiments show that semantic matching matters:
- Using top-10 retrieved rules (vs full playbook) gave faster execution and better accuracy than random selection.
- Random retrieval reduced latency similarly, but accuracy was much worse—showing that the improvement comes from good rule-query matching, not just shortening prompts.
Failure Memory Bank (FMB): learn from verified mistakes
One of the most interesting ideas here is that the system doesn’t just store “rules.” It stores verified failures.
- When the model produces an incorrect result confirmed against ground truth, the Reflector distills:
- the error,
- the root cause,
- and a reusable key insight.
- FMB then retrieves similar past failures to help the Reflector diagnose future attempts.
This is how the tutor becomes better at the recurring failure modes that prompt-only solutions tend to ignore.
Adversarial curriculum: stress test to uncover hidden gaps
DeepEdu-v1 also includes a lightweight adversarial stress-test generator that periodically creates plausible “challenging” cases conditioned on the current playbook. Those are used to trigger the Generator–Reflector–Curator loop just like normal failures.
Important nuance: because the adversarial target is produced by the system itself (not independently verified), it’s treated as stress testing—not as definitive proof of correctness. But it still helps expose missing rules.
What the experiments show when SCR + playbook learning work together
The paper evaluates components separately and then together in the deployed configuration.
Component results: SCR alone and agentic loop alone
- SCR alone: reduces prefill latency while keeping retrieval accuracy strong on long-context benchmarks like
InfiniteBenchandRULER. - Agentic layer (with ablations):
- Adding RAE improves execution by focusing the Generator on relevant playbook rules.
- Adding an adversarial curriculum surfaces latent weaknesses (especially helpful for boundary cases).
- Adding FMB stabilizes behavior across tasks and improves interactive recovery.
The experiments were run with fixed supervision (ground truth labels or deterministic environment outcomes), which matches the “build reliable knowledge first, then deploy” logic required for tutoring.
Deployed configuration: about 2× faster time-to-first-token
When running the agent on top of SCR, DeepEdu-v1 shows clear latency improvements:
- AppWorld Normal:
- TTFT drops from
11.96sto5.51s(2.17× faster, about 53.9% reduction)
- TTFT drops from
- AppWorld Challenge:
- TTFT drops from
12.02sto5.75s(2.09× faster, about 52.2% reduction)
- TTFT drops from
The paper also explains why per-token decode speed stays good: SCR builds on TokenSelect, which includes a selection cache that helps reduce decode latency.
Accuracy/quality improvements from the self-improving playbook
For complex reasoning tasks, the self-improving agent breaks through the underlying baseline ceiling:
- performance improves from 70.0% to 79.5% on the reported metric (described for their agentic benchmark results)
Even better, the gains aren’t just limited to static questions—the agentic improvements also matter in multi-turn interactive settings.
Key Takeaways
Key Takeaways
- DeepEdu-v1 targets real deployment constraints, not just model capability: on-premise data sovereignty, fast long-context inference, and curriculum grounding to reduce hallucinations.
- SCR (Similarity Chunk Rolling) is the efficiency engine:
- clusters similar sub-chunks and runs retrieval once per cluster,
- cuts prefill TTFT by ~35% in long-context tests,
- reduces retrieval calls by 7.7× with strong accuracy preservation (and notable gains on structured retrieval like
R.KV).
- The agentic playbook layer improves tutoring without retraining weights:
- Generator–Reflector–Curator updates structured, auditable rules,
- RAE keeps prompts small and relevant,
- FMB stores verified recurring mistakes for better diagnosis,
- an adversarial curriculum stress-tests the playbook to uncover missing rules.
- Together, they compound: in the deployed agent setup (AppWorld), DeepEdu-v1 cuts time-to-first-token by about 2× (2.17× on normal, 2.09× on challenge).
- Why this matters for Vietnam: this is a path toward trustworthy AI tutoring that stays local, stays aligned to SGK-like knowledge, and stays fast enough for classroom use—without requiring massive retraining cycles.
If you want, I can also turn this into a “how schools could implement DeepEdu-v1-style tutoring” checklist (data setup, playbook curation workflow, and evaluation plan) tailored to Vietnamese curriculum use.
Sources Used
This article is a plain-English breakdown of the following peer-reviewed preprint. Read the original for full methodology and results:
- DeepEdu-v1: Efficient and Scalable Agentic LLMs for Vietnamese Education — arXiv
- Authors: Authors: Quang Nguyen, Hieu Nguyen, Hien Hoang, Toan Pham, Cong Tran, Nam Vu