The Short Answer
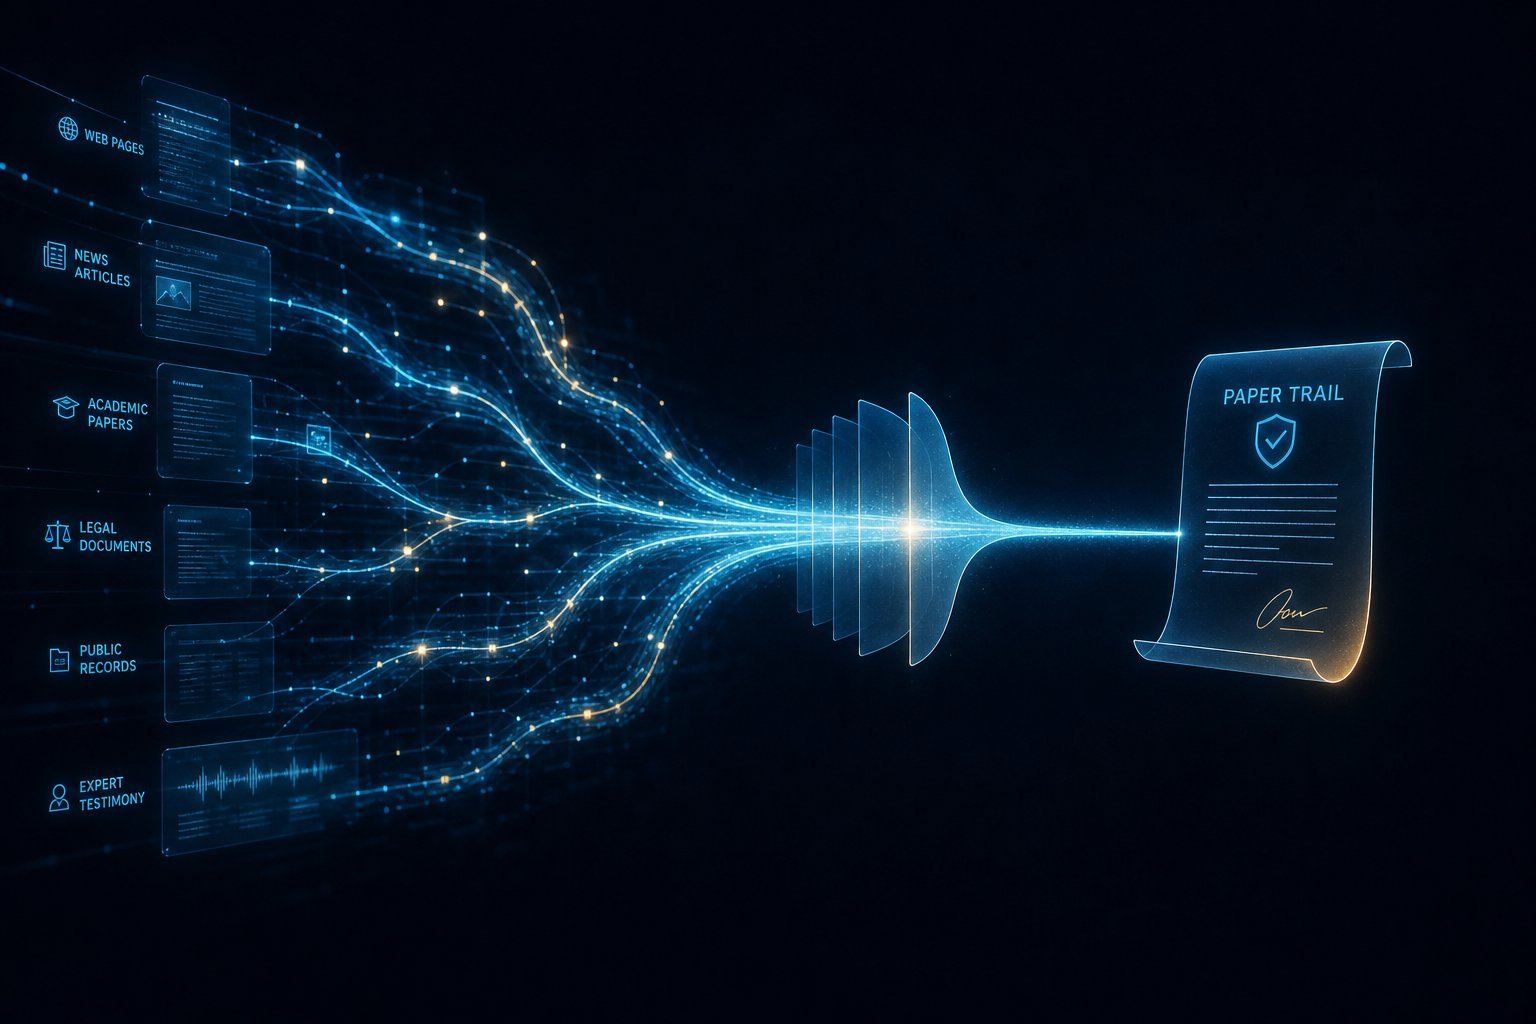
Idea2Prior retrieves and ranks up to five papers from informal research ideas using an auditable pipeline that tracks evidence and filtering—rather than relying on exact keyword overlap. It combines abstract-level assessment, semantic citation expansion, and limited PDF evidence acquisition before joint expert ranking.
For practitioners, this changes the workflow from “hope the search works” to “verify why each match appears,” helping you surface relevant prior work even when the key mechanism isn’t stated in the abstract.
The system’s retrieval-only focus and bounded PDF acquisition mean results depend on what evidence it can retrieve; it can also fail for harder queries, so the audit trail is essential for debugging.
On this page
- Introduction: When you remember the idea, not the paper
- Why This Matters
- Main Content Sections
- How Idea2Prior turns an idea into a ranked list (and keeps it auditable)
- The retrieval-only mode: what it does, and what it intentionally doesn’t
- A guided look at the candidate funnel: from facets to Expert scoring
- What the benchmark measured—and what the numbers actually say
- Practical implications: using Idea2Prior-like workflows in real literature search
- Key Takeaways
Idea2Prior: Auditable paper search from vague research ideas
Introduction: When you remember the idea, not the paper
Ever tried to Google something like “a circuit transformation that only works if the constraint is satisfied” or “an assistant that notices when the task changes mid-stream”? Chances are you can describe the idea pretty well—yet the right paper never shows up, because the vocabulary, setting, and even the “distinguishing trick” might not be stated in the abstract.
That’s exactly the problem space tackled by new research from the original paper: Idea2Prior, an auditable system for retrieving and ranking papers from informal research ideas. Instead of assuming a query and the target paper share the same keywords, the approach is designed to handle synonyms, missing mechanisms in abstracts, and the reality that “close concept” isn’t the same as “same terminology.”
What makes this work stand out is not just the end ranking—it’s the fact that the system is built to be inspectable. It tracks candidate identities, what evidence was available (abstract vs. selected PDF passages), what filtering happened (and why), and where things can fail. That means you can tell the difference between “the system never found the candidate” and “it found it but dropped it later.”
Why This Matters
This matters right now because most real research starts messy. You rarely begin with a perfect title string. You begin with a thought, a half-remembered mechanism, or a “this resembles X, but with a twist.” If AI assistants can only do keyword matching, they’ll keep missing the part that actually connects your idea to prior work.
A very practical scenario: imagine you’re writing a new method for a domain like continual learning. You remember the shape of the contribution—say, “regularize gradients based on a task change detector”—but the paper you need might never say “gradient regularization” in the abstract, or might use a different term like “stabilization” or “adaptive constraints.” An idea-to-paper retrieval tool like Idea2Prior could surface the likely candidates early enough that you don’t waste days rediscovering a solved problem.
And compared to earlier AI research tools that focus on broad exploration and long-form synthesis (for example STORM-style multi-perspective research workflows), Idea2Prior targets a narrower but crucial endpoint: given an idea, return the top five identifiable papers that match it—along with evidence you can audit. It also explicitly treats retrieval as different from writing a great report, which is an important mindset shift if you care about scientific traceability.
Main Content Sections
How Idea2Prior turns an idea into a ranked list (and keeps it auditable)
At a high level, Idea2Prior takes a research idea and returns an ordered list of up to five distinct papers (called the top-R_q). Each entry includes bibliographic identity fields plus a short explanation grounded in evidence the system actually used.
The key design choice is to separate the workflow into stages:
- Cheap, broad candidate discovery and assessment (abstract-level reasoning)
- Citation expansion to find “neighbors” that might share mechanisms even when keywords differ
- Bounded full-text acquisition (PDF evidence), but only for a small number of candidate papers
- Joint Expert ranking over a shortlist
This pipeline is intentionally built so you can debug it. The system doesn’t just output a final list and hope for the best. It preserves intermediate records: candidate identities, which candidates survived filtering, whether a PDF was successfully acquired, and what the Expert ultimately saw.
A useful analogy: think of it like a lab workflow where you don’t skip to the final result until you’ve verified reagents. Abstract-level signals are your initial screening. PDF evidence is your confirmatory measurement. And the audit trail is the lab notebook that tells you whether you failed because the hypothesis was wrong, the screening removed a real contender, or the “measurement device” (PDF access) didn’t work for a particular paper.
This auditable workflow is part of what makes Idea2Prior different from “black box” Deep Research experiences. You can’t always guarantee that the PDFs are available—so the system is designed to still rank correctly even when full text is missing.
The retrieval-only mode: what it does, and what it intentionally doesn’t
One reason Idea2Prior is interesting is that it supports a retrieval-only execution mode. This is designed to avoid the extra work involved in producing long reports or deep synthesis artifacts.
In retrieval-only mode, the system:
- still assesses candidates using complete available abstracts
- still performs semantic citation expansion
- still attempts local PDF acquisition for selected papers—up to five fixed paper slots
- still feeds the Expert model with abstracts plus only the PDF evidence that was actually acquired
Importantly:
- If a PDF is unavailable, the system does not replace it with another paper to “make up” for missing evidence.
- A missing PDF does not automatically mark a paper irrelevant.
- The Expert ranking is still made from a combination of abstract-level evidence and whatever PDF snippets were successfully extracted.
It’s a practical constraint: retrieval in the real world is messy. Paywalls, missing archives, partial downloads—so the system is built to handle those realities without pretending everything always works.
For context, Idea2Prior also has an optional full-report mode that adds report-specific extraction and synthesis artifacts. But the retrieval benchmark comparison focuses on retrieval-only behavior, so the evaluation is closer to “find the right papers” than “write the perfect literature review.”
A guided look at the candidate funnel: from facets to Expert scoring
The pipeline uses “facets” to represent what the query idea implies. After the system receives an idea q, it derives multiple technical facets—typically 3 to 7—such as:
- problem/setting/method cues
- mechanism-level hints
- assumptions and structural signals
These facets help the system bridge the vocabulary gap. If the idea uses “constraint satisfaction” terminology while the target uses “feasibility conditions,” the facets and neighbor expansion can still push the right works upward.
Local selection: budgeted filtering (and why it can still drop relevant papers)
Idea2Prior doesn’t evaluate every discovered candidate forever. It uses a budgeted selection algorithm that resembles a scored shortlist based on title and complete available abstract text, with BM25-like scoring and explicit handling of:
- publication-year eligibility (the benchmark is 2015–2025, with verified preprint versions consolidated)
- duplicates and entity normalization
- “protected relevance” behavior for corroborated seeds and strongly retrieved items
A crucial detail: this stage is not guaranteed recall. It’s designed to manage workload, not to prove that the relevant candidate will always survive.
Abstract assessment labels: overlap grades that don’t pretend to be probabilities
When scoring abstract-level overlap, the system produces an ordinal overlap label with 33 for high overlap, 22 for partial, 11 for adjacent, and 00 for no overlap. It also tracks covered facet IDs and similarities in task/method/structure.
And they’re explicit about a common misconception: these labels are decision evidence, not calibrated “how relevant is this with probability 0.7” outputs. The system also preserves failure states rather than converting missing/invalid model outputs into fake zero scores.
Semantic citation expansion: where “different words” gets handled more directly
After initial assessment, up to five papers (seeds from candidates) are used to trigger semantic citation expansion via Semantic Scholar. For each seed, a set of unique citation neighbors with abstracts is assessed in batches (up to 20 at a time).
A “light-role” model evaluates neighbor papers by:
- taking the original query and derived facets
- checking for synonymy and mechanism-level matches
- avoiding the trap of assigning zero relevance purely because a keyword is absent
The system then filters out invalid “zero-score” neighbors and keeps positive neighbors in an ordered manner. It also enforces caps (example: up to 15 retained per seed under the default setting), while globally maintaining a hard limit on how many assessed works reach the Expert.
Joint Expert ranking: only the evidence that actually arrived
Finally, the Expert model gets:
- up to 60 eligible works (shortlist cap)
- complete abstracts for those works that have them
- existing abstract assessment info
- PDF material only for paper slots that were successfully acquired
The PDF evidence is not a random chunk either. For each available PDF, the local extractor grabs up to six windows of text (max 1,800 characters per window, half-window stride), chosen using lexical scoring plus section cues. These are marked as partial, with page offsets and hashes stored locally.
Then the Expert outputs exactly min(5, |C_q|) ranked candidate IDs (five unless fewer eligible candidates exist), each with a short qualitative explanation and an evidence-source label.
This is one of the most auditable parts: the ranking is grounded in what was actually captured, and the audit checks verify candidate membership, identity deduplication, rank consistency, and whether the claimed evidence sources match the evidence that was supplied.
What the benchmark measured—and what the numbers actually say
The evaluation is based on 30 queries, split into 10 each from three prompt difficulty tiers: EASY, MEDIUM, and HARD. The dataset construction specifies shared targets across tiers, but the paper matching task remains difficult because prompt specificity changes:
- EASY: more identifying detail
- MEDIUM: less detail removed
- HARD: short and less specific descriptions
The comparison uses the first ten query IDs per tier:
- EASY: N001–N010
- MEDIUM: C001–C010
- HARD: C001–C010
Each system gets the same filled item prompt with:
- constraints (2015–2025, verified preprint versions consolidated)
- instructions to return up to five distinct works with bibliographic fields and explanations
- identity verification and deduplication requirements
- the idea text
A key metric is Hit@5 (target recovery within the returned top five). The paper reports a historical comparison under a documented accounting convention. Aggregate reported Hit@5 is:
| System | Aggregate Hit@5 (30 queries) |
|---|---|
Idea2Prior |
53.3% (reported as 16/30) |
ChatGPT web Deep Research |
43.3% (13/30) |
Gemini web Deep Research |
36.7% (11/30) |
The authors also note a nuance: ChatGPT includes one credit based on a historical convention (“counted hit” even if it wasn’t observed in the final outputs under a certain convention). If you counted only observed hits, ChatGPT’s EASY would drop from 7/10 to 6/10, and aggregate recovery would become 12/30—but the main table preserves the earlier convention explicitly.
Tier behavior: Idea2Prior wins EASY/MEDIUM, but not HARD
The advantage is not uniform across difficulty levels. The paper states:
- Idea2Prior leads the browser baselines by 20 percentage points on EASY and MEDIUM
- but it trails ChatGPT by 10 points on HARD
So the “vibe” of the results is clear: when the idea includes enough identifiable cues, Idea2Prior’s abstract + neighbor expansion + auditable PDF evidence helps. But when the idea is very short and fuzzy, the model may struggle more than the broader web-based Deep Research competitor (at least under the historical setup).
Time and cost observations: slower on latency, low observed API cost
On runtime: the paper reports mean selected-run latency around 8 minutes 53 seconds (and also mentions mean selected-run latency of 8.89 minutes in another place). That’s longer than operator-reported browser averages:
- ChatGPT web: 5.2 minutes
- Gemini web: 4.7 minutes
There’s also a separate nine-query API cost sample averaging $0.0945 per task. The authors emphasize this is a historical cost observation, not a controlled matched comparison with subscription or browser Deep Research billing models.
Coverage disagreement: different systems return different evidence sets
They also check pairwise agreement (which captures overlap in returned top papers ignoring rank). Coverage between systems ranges from 6% to 34%, meaning the systems often produce different top-5 lists for the same idea. That matters because it suggests complementarity: even if one system gets the target more often, others may surface alternative strong candidates.
Practical implications: using Idea2Prior-like workflows in real literature search
If you’re building or using an AI research assistant, this paper offers several concrete lessons.
1) “Auditable retrieval” is not a luxury—it’s how you trust paper recommendations
When your assistant returns five papers, you need to know why those papers were chosen and what evidence was actually available. Idea2Prior’s approach—storing identity checks, filtering reasons, and PDF acquisition outcomes—makes it possible to diagnose failure modes.
If you’re a researcher, that means you can stop asking “is the assistant smart?” and instead ask “did it miss because the candidate was never discovered, or because evidence was missing?”
2) Retrieval-only is a strong product wedge
The retrieval-only design avoids report-generation overhead. In real workflows, people often want:
- “Give me the most likely 5 papers”
- then “I’ll read and write”
rather than “Write a full literature review for me.”
Idea2Prior explicitly treats this as a distinct task from synthesis quality—and backs it with a benchmark focused on retrieval accuracy (Hit@5).
3) Abstract-only can still work, but partial full-text evidence helps
The system’s ability to rank even when PDFs are unavailable is important. Many literature tools break when full text can’t be acquired. Idea2Prior instead treats PDF access as optional evidence that may boost confidence but shouldn’t invalidate the paper.
In the real world, this reduces brittle failure when archive access is incomplete.
4) Difficulty-aware behavior is essential
Results concentrate in EASY and MEDIUM, with HARD being the “problem child.” That doesn’t necessarily mean retrieval from very short ideas can’t work—it likely means you need stronger prompt grounding, better idea decomposition, or richer discovery signals when specificity is missing.
In other words: Idea2Prior shows a clear path for improving retrieval from fuzzy ideas, but also shows where the current machinery hits limits.
And if you want to see what this looks like operationally, you can go back to the original project description in the paper on arXiv, which details the retrieval-only pipeline and the audit-oriented design goals.
Key Takeaways
- Idea2Prior targets idea-to-paper retrieval, returning up to five ranked papers even when query wording doesn’t match paper terminology.
- The workflow is auditable: it preserves candidate identities, abstract assessment evidence, filtering outcomes, and the status of PDF acquisition attempts.
- In retrieval-only mode, it ranks using complete available abstracts plus only the PDF evidence that was successfully acquired (missing PDFs don’t automatically disqualify papers).
- In a historical 30-query benchmark, reported aggregate Hit@5 is 53.3% for
Idea2Prior, vs. 43.3% forChatGPTweb Deep Research and 36.7% forGeminiweb Deep Research. - The advantage is strongest on EASY and MEDIUM, while
ChatGPTcan lead on HARD (shorter, less specific idea prompts). - Reportedly, selected-run latency is about 8.89 minutes on average, and a separate nine-query API cost sample averages $0.0945 per task (not a matched billing comparison).
- Returned top-5 lists often disagree across systems (pairwise coverage 6% to 34%), suggesting opportunities for hybrid workflows or ensemble retrieval.
- For practical use: treat these tools as evidence-grounded paper finders, not as proof engines—then use the audit trail to decide what to read next.
If you’d like, I can also rewrite this into a “how to implement an auditable retrieval pipeline” checklist, using Idea2Prior’s stages as a blueprint.
Sources Used
This article is a plain-English breakdown of the following peer-reviewed preprint. Read the original for full methodology and results:
- Idea2Prior: Auditable Paper Retrieval and Ranking from Research Ideas — arXiv
- Authors: Authors: Shitian Yang, Ruijie Tao, Jian Huang