The Short Answer
GenVerOpt helps AI reason visually without relying on language by generating multiple candidates, verifying them, and optimizing iteratively toward the best visual answer. This directly targets AI’s weak spot in non-verbal visual reasoning such as abstract pattern completion and ambiguous region delineation.
Practically, it turns visual prediction into a testable reasoning loop: the system can re-evaluate uncertain boundaries and improve results rather than outputting a single label once. The approach is designed to optimize per sample, not only rely on dataset-level patterns learned during training.
The key caveat is that the paper’s success depends on having an effective verifier to score candidates, and visual reasoning remains harder than verbal reasoning because intermediate steps are not naturally explicit.
On this page
- Introduction
- Why This Matters
- GenVerOpt’s Core Idea: Think Like “Generate → Check → Improve”
- Case Study 1: Visual IQ Puzzles Where Machines Previously Wobble
- Case Study 2: Prostate Cancer Segmentation—Reasoning Under Ambiguous Boundaries
- Case Study 3: Liver Vessel Segmentation—Enforcing Structural Coherence
- Case Study 4: Tumour Alignment Between MR and Ultrasound—Choosing Correspondences Under Deformation
- What This Suggests About Visual Non-Verbal Reasoning (Beyond This Paper’s Demos)
- Key Takeaways
Can AI Reason Visually Without Language? GenVerOpt
Introduction
Most people can “reason” with their eyes—puzzles, maps, diagrams, medical scans, you name it. But modern AI has a weird blind spot: it’s great at reasoning in language, and decent at solving lots of structured problems, yet it still struggles when the task is purely visual non-verbal reasoning. Think abstract pattern completion, deciding what region in an image actually matters, or drawing clean boundaries when the difference between “inside” and “outside” is subtle and ambiguous.
This gap is exactly what new research tackles in the paper behind this blog: “Can machines reason non-verbally?” by Shaheer U. Saeed, Zion Tse, Gregory Slabaugh, Daniel C. Alexander, and Yipeng Hu (see the original paper). The authors argue that current systems—yes, including top chat and vision models—often fail because they don’t really do the kind of iterative, checkable “thinking” humans do when reasoning visually.
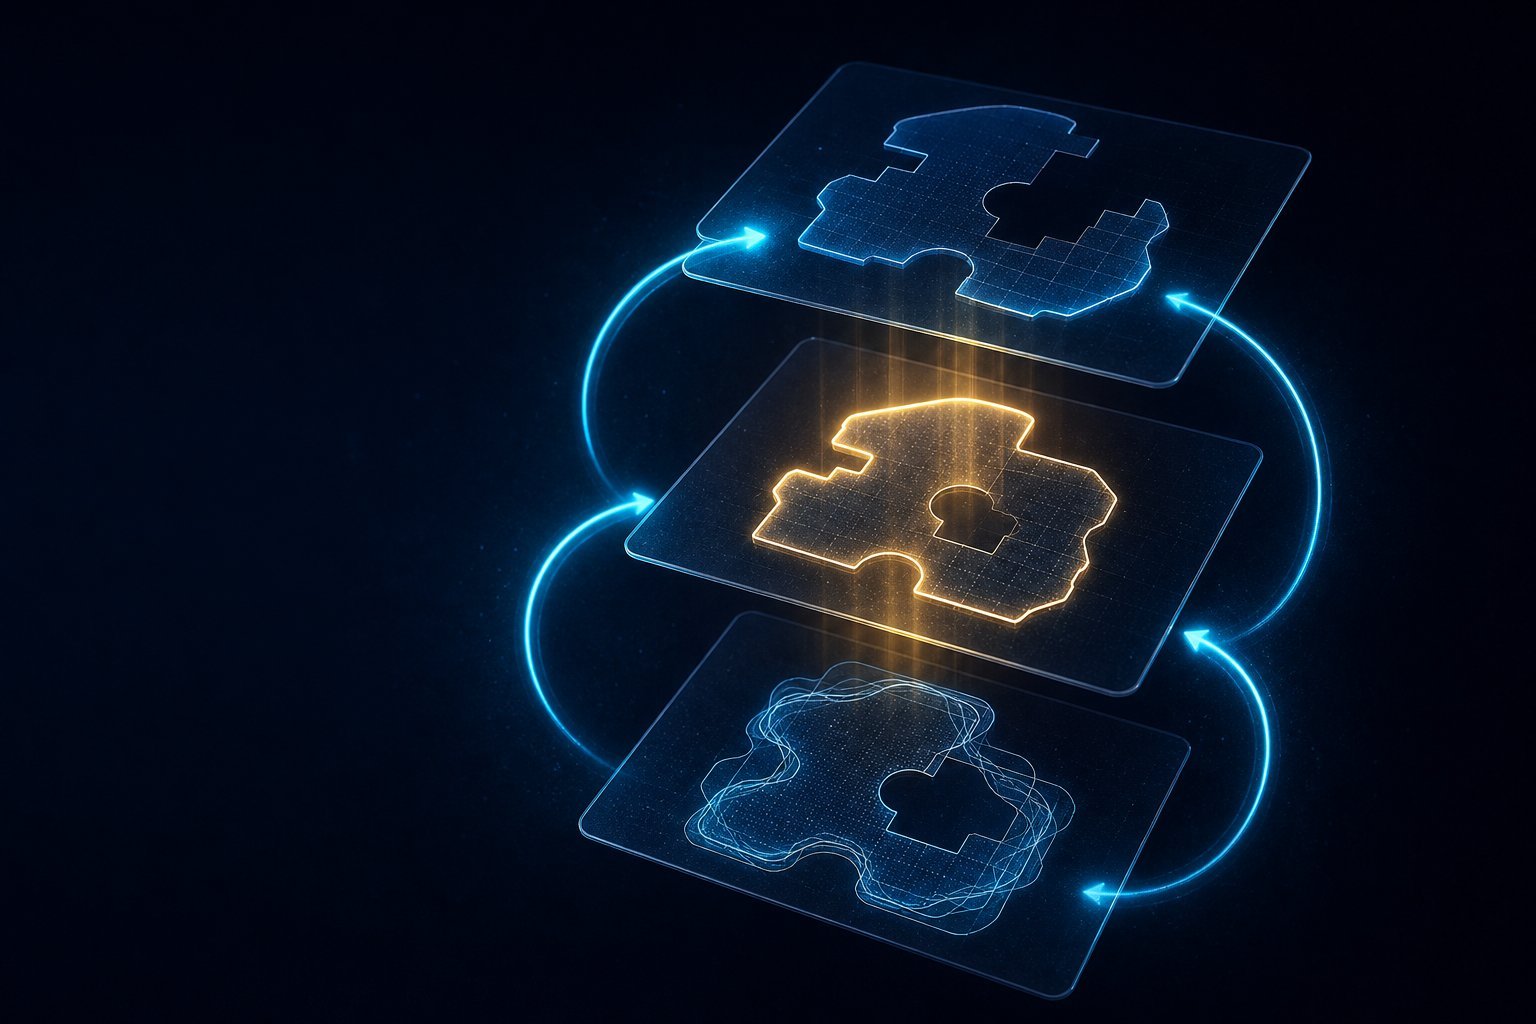
Their proposal is called GenVerOpt: a general framework that unifies generation, verification, and optimisation into one reasoning pipeline for machines. Instead of producing a single guess and hoping it’s right, the system generates multiple candidates, checks them with a verifier, and iteratively improves toward the best answer—very similar to how humans deliberate when a problem isn’t straightforward. And the paper shows results across abstract IQ puzzles and demanding medical imaging tasks.
Why This Matters
Here’s why this research feels timely: we’re pushing AI into real-world settings where “language” is an unreliable interface. In medicine, for example, clinicians can’t always explain what they see in a scan in words. They need the AI to figure it out visually, under uncertainty, and ideally produce a result that makes structural sense—not just pixel-level similarity.
A concrete scenario where this could help today: imagine a prostate cancer workflow where an imaging AI proposes a tumour boundary, but you—like most clinicians—immediately notice it’s a bit off in ambiguous regions. Instead of treating the AI output as final, GenVerOpt-style reasoning would let the system try multiple plausible boundaries, score how correct each seems (via a verifier), and refine until the uncertainty is resolved. In other words, the model would behave less like a “single-shot labeler” and more like a cautious assistant who can re-evaluate its own visual reasoning.
This also builds on a key trend in AI research: moving away from “one forward pass, done” systems toward testable reasoning loops. Previous approaches often improved either generation quality or evaluation quality. What GenVerOpt adds is a unifying recipe: make verification central, then optimise per input—not just during training. That’s a meaningful step, because visual tasks often have huge solution spaces and ambiguous near-misses, where “being close” is not the same as being correct.
GenVerOpt’s Core Idea: Think Like “Generate → Check → Improve”
The paper’s central claim is pretty intuitive once you hear it: humans reason longer when the problem is hard. Psychological work (cited in the paper) suggests that extended thinking time helps because we can consider multiple strategies, imagine possible outcomes, evaluate them, and then pick the best option.
GenVerOpt turns that into a machine pipeline with three steps:
- Generation: propose multiple candidate solutions (not just one).
- Verification: estimate how correct each candidate is.
- Optimisation: refine candidates over iterations to find the best one.
Why this matters more for visual reasoning than language
In language-based reasoning, intermediate steps can often be explicit and checked. If a model outputs a chain of logic, you can verify each step. For visual reasoning, the “intermediate reasoning” is usually hidden inside the model’s internal representations—there’s no obvious intermediate trail you can validate.
So the paper argues that non-verbal reasoning is tough partly because the system can’t easily tell whether it’s going wrong until too late. GenVerOpt tries to fix that by making verification a first-class component.
A helpful analogy: proofreading draft paragraphs
Imagine you’re writing an essay. Getting a good paragraph is hard. Recognising that a paragraph is bad is easier. That maps onto why generation is difficult and verification can be easier:
- Generation is like producing many drafts in a huge space of possibilities.
- Verification is like reading drafts and judging which ones make sense.
GenVerOpt leans into that asymmetry: generate candidates (possibly imperfect), then invest in verification to filter what’s likely correct, and iterate.
What’s different from standard deep learning training?
Standard deep learning usually optimises dataset-level performance: train once, then infer on new inputs.
GenVerOpt instead does per-sample optimisation at inference time. So even if the model has biases learned during training, the system can still “think” for each new image by sampling multiple solutions and refining them via feedback from the verifier.
The paper explicitly links this to a common issue: models can get stuck in local optima shaped by dataset bias, label subjectivity, or limited diversity. Per-sample optimisation reduces how strongly those dataset-level quirks trap the system.
Case Study 1: Visual IQ Puzzles Where Machines Previously Wobble
One of the paper’s smartest moves is starting with a benchmark where the “right answer” is unambiguous—classic visual IQ puzzles. These puzzles require abstract reasoning like identifying a hidden rule across grids or sequences. The task isn’t just pattern recognition; you must actually understand transformations and continuities.
How GenVerOpt is implemented for IQ puzzles
This is where GenVerOpt shines because it’s easy to control the complexity:
- Generation is trivial: all candidate answers are pre-defined, and the correct one is guaranteed to exist among them.
- Verification is the real challenge: determine which candidate correctly completes the pattern.
The authors train a verifier network that takes a puzzle grid with a candidate option inserted into the missing location. Each completed grid is labelled as correct or incorrect. Then, for a smaller task-specific set of movement puzzles, they fine-tune the verifier using 32 temporal movement puzzles.
At inference time, GenVerOpt scores each candidate using the verifier and picks the one with the highest predicted correctness. Since the solution space is small and fully enumerated, optimisation becomes essentially exhaustive search over candidates.
What the results show (and why the “graded” scores matter)
The paper reports that GenVerOpt outperforms all tested machine reasoning models and even human participants on 379 temporal movement puzzles.
A particularly telling detail: GenVerOpt doesn’t just output a binary “right/wrong” guess. It produces ranked probabilities, and the ranking reflects semantic closeness. For example, clearly incorrect candidates get the lowest scores, while spatially adjacent alternatives—plausible but still wrong—receive higher confidence than totally unrelated options.
That pattern suggests the verifier isn’t merely picking up superficial cues. It appears to learn something closer to the underlying structure—like skipping, ordering, or continuity relationships.
| Model / Method type | Main bottleneck observed in IQ puzzles | GenVerOpt advantage |
|---|---|---|
| Existing machine reasoning models | Near chance accuracy (~25%) and difficulty with abstract visual concepts | Learns a verifier that ranks candidates by plausibility; exhaustive selection finds the correct answer |
Case Study 2: Prostate Cancer Segmentation—Reasoning Under Ambiguous Boundaries
If IQ puzzles are about “right vs wrong,” medical segmentation is about something messier: uncertainty. In prostate cancer MR images, tumour borders can be subtle and inconsistent across patients and imaging sequences. Even experts can disagree, and the space of “almost right” segmentations can be huge.
That makes this a perfect stress test for any reasoning system.
Why verification is harder in segmentation
Unlike IQ puzzles, segmentation doesn’t have a single obvious correct answer you can rank cleanly. There can be many near-correct segmentations, and small boundary shifts can matter.
So the paper doesn’t treat verification as a simple classifier over enumerated options. Instead, it frames segmentation as a combined generation + verification problem where both modules adapt.
Joint generation–verification training
For prostate segmentation, the authors use a generator–verifier setup inspired by adversarial-style ideas: the generator proposes segmentations, and the verifier predicts how correct they are.
During training:
- Expert or consensus segmentations are treated as probability 1 (fully correct).
- Generator outputs are treated as probability 0 (incorrect).
They use meta-learning with Reptile to encourage generalisation across related segmentation tasks, and then fine-tune on the target task using only 64 task-specific training examples.
Optimisation via RL self-play
Now for the key reasoning loop: they use reinforcement learning (RL) self-play. Two copies of the generator propose candidate segmentations; the verifier scores them; the higher-scoring output is rewarded and the other is penalised. This creates a natural pressure toward candidates that are not just plausible-looking but actually consistent with the verifier’s notion of correctness.
Crucially, generation is probabilistic (sampling from logits), so the system explores a broad set of plausible candidates. That helps avoid getting trapped in dataset biases.
Results: beating state-of-the-art, matching expert level with limited data
The paper reports that GenVerOpt:
- substantially outperforms state-of-the-art automated methods for prostate cancer segmentation (statistically significant gains).
- exceeds the accuracy of a human imaging expert while performing at the level of a trained clinician.
- achieves this with only 64 task-specific examples used for initiating optimisation.
An especially practical detail is that GenVerOpt refines tumour boundaries even when the initial deep learning prediction looks visually similar to the final answer—meaning the reasoning loop can correct subtle mistakes rather than just smoothing or copying patterns.
| Task | Data regime stated in paper | What GenVerOpt specifically improves |
|---|---|---|
| Prostate cancer segmentation | Optimisation initialized with 64 labelled samples | Boundary refinement under ambiguity; improved tumour delineation beyond “confident-looking but wrong” outputs |
Case Study 3: Liver Vessel Segmentation—Enforcing Structural Coherence
Vessels are tricky for a different reason: they’re not just “areas.” They’re networks—branching structures that must connect in anatomically coherent ways. Overlapping intensities, occlusions, and irregular vessel morphology create lots of traps for models that optimise locally.
This is structural visual reasoning: getting the relationships right, not just the appearance.
How GenVerOpt is adapted for vessels
The paper keeps the same generator–verifier framework style used for prostate segmentation, fine-tuned with only 64 vessel annotations.
But it adds an important training trick: they include artificially broken vessels during verifier training. That teaches the verifier to penalise segmentations with discontinuities, pushing optimisation toward globally coherent vessel trees.
Results: matching human-level Dice, improved topology
GenVerOpt achieves a Dice score on par with a trained human observer, while beating state-of-the-art automated methods.
But the standout result isn’t only voxel overlap. They also evaluate structural correctness:
- GenVerOpt reconstructs vessel hierarchies with a higher proportion of correct parent–child assignments than baselines.
- it even slightly surpasses human performance in statistical significance settings (human measured as a single expert segmentation compared against a consensus ground truth from three experts).
Qualitatively, GenVerOpt produces fewer broken or disconnected vessels, consistent with the reasoning idea of enforcing structure through repeated generation and verification.
Case Study 4: Tumour Alignment Between MR and Ultrasound—Choosing Correspondences Under Deformation
The final medical case study is about aligning prostate tumour regions between pre-operative MR and intra-operative ultrasound (US). This is notoriously hard because tissues deform during surgery, appearance changes across modalities, and tumours can be partially occluded.
Here, “reasoning” means inferring the most plausible correspondence—basically asking: which region in US matches the tumour boundary pattern seen in MR?
Generation via SAM plus learned prompts
For generation, the paper uses Segment Anything Model (SAM) to produce segmentation regions, but prompts must be predicted.
They introduce a prompt-predicting neural network that outputs paired locations across both modalities. Using positive-only prompts, they generate segmentations for US and MR, sampling 16 corresponding prompts total per image pair.
Then they compute a dense displacement field that warps US toward MR alignment.
Verification uses two complementary scores
Verification combines:
- Dice overlap between SAM-segmented regions after registration
- SSIM (structural similarity index) between the warped and fixed images
This dual scoring helps ensure both anatomical correspondence and overall image consistency.
Optimisation trains prompt prediction with RL
Optimisation again uses reinforcement learning. Candidate prompt sets are proposed; the verifier scores alignment; the RL loop trains the prompt-predicting network to maximise verification scores (Dice + SSIM).
Evaluation uses:
- Target Registration Error (TRE) on unseen landmarks (normalised using 12.5mm as the maximum error assumed when unaligned)
- Dice overlap on anatomical structures like the prostate gland (kept separate from the generation/verification internals)
GenVerOpt achieves statistically significantly higher Dice overlap and lower TRE compared to leading registration methods, suggesting it can generalise to patient-specific deformations rather than just fitting a narrow supervised pattern.
What This Suggests About Visual Non-Verbal Reasoning (Beyond This Paper’s Demos)
One of the paper’s main conclusions is that non-verbal reasoning can be a foundation—not an afterthought—for more general machine intelligence. The reason is structural:
- Visual reasoning tasks often have implicit intermediate reasoning steps that are hard to verify directly.
- GenVerOpt sidesteps this by making verification explicit through a learned verifier.
- It then uses optimisation to turn verification into an iterative improvement signal—more like deliberation than inference.
Also, the paper’s framework is intentionally general. The case studies vary a lot:
- abstract IQ puzzles (candidate enumeration + verification),
- ambiguous medical segmentation (probabilistic generation + RL optimisation),
- structural vessel topology (verifier penalising breaks),
- cross-modality registration (generation as prompt-guided segmentations + verifier scoring).
Even though the implementations differ, the skeleton stays the same: generation → verification → iterative optimisation.
And importantly, the paper’s theme isn’t “need more labels.” Across the medical tasks, GenVerOpt repeatedly shows strong performance with limited task-specific examples (notably 32 for fine-tuning in one IQ subset, and 64 labelled samples used for optimisation initiation in segmentation tasks).
That’s relevant because label scarcity is one of the biggest real bottlenecks in deploying AI for high-stakes visual domains.
Key Takeaways
- Machines still struggle with visual non-verbal reasoning, even when they’re strong in language and logic.
- The research introduces GenVerOpt, a framework that performs reasoning via generation, verification, and optimisation—mirroring human “imagine → evaluate → refine” thinking.
- On 379 temporal movement IQ puzzles, GenVerOpt outperforms existing machine models and human participants, achieving robust abstract visual reasoning.
- For prostate cancer segmentation, GenVerOpt matches clinician-level performance and outperforms state-of-the-art, using only 64 task-specific training examples to initialise optimisation.
- For liver vessel segmentation, it achieves Dice on par with a trained human observer while improving structural correctness (fewer broken vessels; better parent–child assignments).
- For tumour alignment between MR and ultrasound, GenVerOpt improves alignment metrics (higher Dice, lower TRE) by learning to propose better correspondences and refining them via verification scores.
- The big practical idea: instead of one-shot predictions, per-sample iterative optimisation guided by a verifier can reduce the impact of dataset bias and help resolve ambiguity.
If you want, I can also rewrite this into a “how it works” diagram-style explanation (with the same content, but structured like a process flow), or tailor the examples to a specific audience—like clinicians, researchers, or ML engineers.
Sources Used
This article is a plain-English breakdown of the following peer-reviewed preprint. Read the original for full methodology and results:
- Can machines reason non-verbally? — arXiv
- Authors: Authors: Shaheer U. Saeed, Zion Tse, Gregory Slabaugh, Daniel C. Alexander, Yipeng Hu