Extract Text from PDF Free - Online PDF Text Extractor
Turn PDFs and photos of pages into clean, editable text.
- PDF, PNG, JPG, WebP
- Markdown, Word, CSV
- Deleted within 60 min
The tool could not start. Reload the page, and check that your browser or an extension is not blocking scripts from this site.
Results
Create a free account for 50 pages a day.50 free pages a day Create free account
Redaction applies to the Rendered view, copies and exports. This editor shows the underlying text.
Secure & Private PDF Processing
- Files auto-deleted after 60 minutes
- Secure session isolation
- Read by Mistral AI in the EU
Privacy and security
What happens to your files
Documents are often personal, so here is exactly what happens to yours, step by step.
You agree before anything leaves your device
The first time you run a file, you are asked to approve sending it to our OCR processor, Mistral AI (France, EU). Nothing is uploaded before you agree, and you can withdraw consent at any time through our contact page.
Your original is deleted as soon as it is read
The uploaded file is removed from our server when the OCR call ends. Only the extracted Markdown and images remain, so you can download them.
Results expire on their own
Extracted text and images are deleted automatically 60 minutes after processing. Delete now in the results toolbar removes them straight away.
Only you can open your results
Every job gets an unguessable ID tied to your session or account. Anyone else who requests it is refused.
Editing, redaction and export stay in your browser
The text you edit is not sent back to us, and Markdown, text, HTML, JSON, Word and CSV exports are built on your device.
We keep usage records to enforce daily limits (for signed-in members the file name, page count and time; for guests a daily counter), never the content of your documents. Send to hands your text to another Prompt Index tool, which processes it under that tool's own terms. Mistral AI states that API data is not used to train its models; the privacy policy sets out the processor's own retention terms.
How it works
How to extract text from a PDF or an image
OCR (optical character recognition) turns a picture of text, such as a scanned page, a photographed receipt or a PDF with no selectable words, into text you can search, edit and copy. This tool uses Mistral AI's OCR model, which keeps headings, lists, tables and maths in the structure of the page, so you get Markdown instead of one block of words.
Add your files
Drop PDFs or images, paste a screenshot, or on a phone tap Scan with camera. A batch can hold up to 10 files.
Check the page count
Pages are counted in your browser before anything is sent, so you see what a run will use from your daily allowance. For a long PDF, enter a range such as 1-3, 7 and only those pages are uploaded.
Let it read
Each file is sent once for recognition. You see real progress through uploading, reading and preparing results, and you can cancel at any point.
Review, export or send
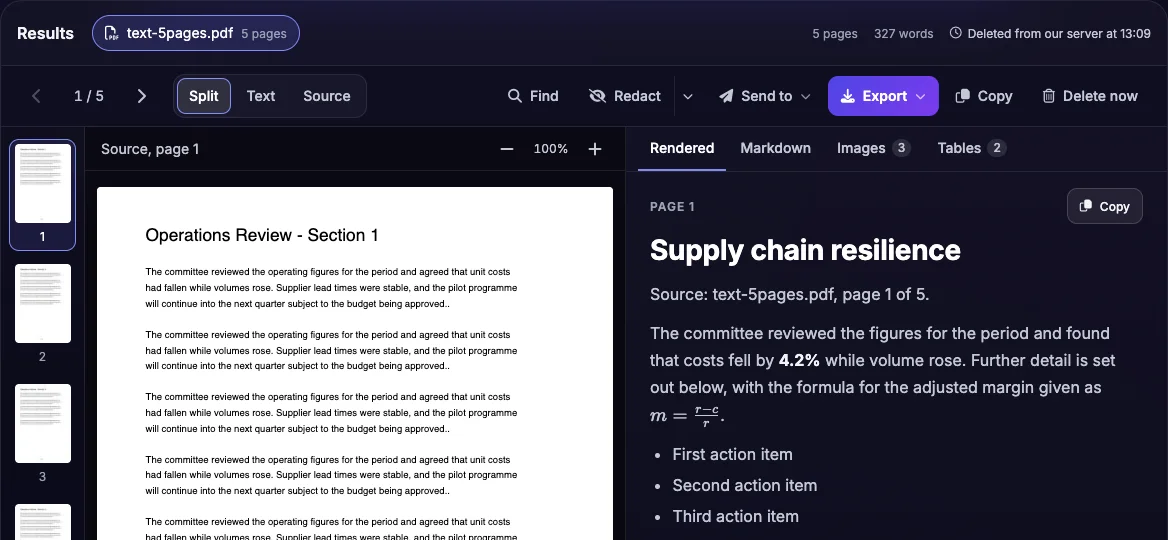
Compare each page with its source, fix anything the OCR got wrong, then download Markdown, text, HTML, Word or JSON, or send the text on to another tool.
Five habits for cleaner results
- Scan at 200 to 300 DPI. Higher rarely helps and makes files larger.
- Hold the camera straight above the page, in even light, with no shadow across the text.
- Crop away borders and fingers; the text should fill most of the frame.
- Avoid heavy JPG compression and filters that crush contrast.
- Split a stack of different documents into separate files so each one reads cleanly.
Features
Everything between upload and export
Plain text is only the start. These are the parts that save the work that usually comes after OCR.
Scans, photos and PDFs
Reads scanned and digital PDFs as well as PNG, JPG and WebP images, including screenshots pasted from the clipboard and photos taken on your phone.
Check before you run
See each file's page count against what you have left today before anything is uploaded, and pick exactly the pages you need.
Side-by-side review
The source page sits next to the extracted text. Click a page to jump to it, edit any page in place, and reset it to the original with one click.
Tables to spreadsheets
Tables are picked out of the text and listed in their own tab. Copy one for Excel or Google Sheets, or download it as an Excel workbook or CSV.
Maths as LaTeX
Equations come back as LaTeX and render in place. If the renderer cannot load, the LaTeX source stays visible.
Export what you need
Markdown, plain text, HTML, JSON, Word (.docx) and a searchable PDF that keeps your original pages with the text hidden beneath, all built from the text on screen so your edits come with you. The PDF text layer is placed per page, so highlights are approximate.
Figures and diagrams
On Basic and Pro, the pictures found inside a document come back as image files, linked from the Markdown and packaged in the ZIP.
Redact before you share
Replace emails, phone numbers, card numbers, IBANs, US and UK national ID numbers, IP addresses and labelled dates of birth with labelled placeholders in your browser. Pattern-based, so it misses names: review the result.
Send it to other tools
Three tools take the text straight from this page and three take a .txt you upload. Long text is cut to each tool's limit, and the Detector needs at least 50 words.
Formats and limits
Supported file types and daily limits
Upload PDF, PNG, JPG and WebP files. One page of a PDF, or one image, counts as one page of your daily allowance, which resets every day and is shown above the upload box.
| Feature | Guestno accountYour plan | Freefree account | Basic$9.99 per month | Pro$29.99 per month |
|---|---|---|---|---|
| Pages per day | 1 | 50 | 250 | 1,000 |
| Largest file | 10 MB | 10 MB | 25 MB | 50 MB |
| Files processed at once | 1 | 1 | 2 | 2 |
| Figures and diagrams as image files | Not included | Not included | Included | Included |
Included on every plan
- Page ranges and page counts before upload
- Side-by-side review and in-place editing
- Tables, maths, redaction and every export format
- Send to the six connected tools (Decision Lab needs Basic or Pro, and Study Studio needs an account)
Not supported
- HEIC, HEIF, GIF, TIFF and BMP images: convert to JPG or PNG first
- Password-protected or damaged PDFs
- Word-by-word text positioning in the searchable PDF: the text layer is placed per page
Use cases
What people use PDF OCR for
The tool is the same; the checks you make afterwards depend on the document.
Invoices and receipts
Photograph or scan the document and line items usually come back as a table you can paste into a spreadsheet. Check every amount against the original, and redact card numbers before you share the text.
Handwritten notes
Neat handwriting is often readable, but expect more corrections than with print. Read the result beside the source page, then polish it.
Polish them in Writing AssistantScanned books and archives
Work through a long scan in page ranges. Headings and lists stay as Markdown, which suits Obsidian and other note apps.
Make quizzes in AI Study StudioAcademic papers
Equations arrive as LaTeX and tables can be exported to CSV. Give reference lists and special symbols a second look.
Verify claims in Search & CiteLegal and contracts
Get searchable text from a signed or scanned agreement, redact emails, phone numbers and ID numbers, then read the text yourself for names and addresses, which the pattern-based redactor does not catch. Verify clause wording against the original: this is a text tool, not legal advice.
Weigh options in Decision LabScreenshots, slides and whiteboards
Paste a screenshot with Ctrl/Cmd+V, or photograph a slide or whiteboard, and copy the words out instead of retyping them.
Alternatives
How PDF OCR compares
No approach wins everywhere. This table describes categories of tool in general terms, so you can see where this one fits.
| Approach | This tool | Desktop OCR software | Phone scanner apps | OCR APIs you integrate |
|---|---|---|---|---|
| Setup | Open the page. A guest can try 1 page; a free account takes a minute. | Install, activate and update software. | Install an app on a phone. | Write and host code, manage keys, storage and deletion. |
| Output | Markdown, plain text, HTML, JSON and Word, a searchable PDF with page-level hidden text, and tables as Excel or CSV. | Often searchable PDFs and Office formats. | Usually a searchable PDF or plain text. | Whatever you build. |
| Structure | Headings, lists, tables and LaTeX maths are kept in the Markdown. | Layout retention varies by product. | Table and maths support varies by app. | Depends on the service you call. |
| Where files go | Sent once to Mistral AI; original deleted when read; results expire in 60 minutes. | Processed on your own computer. | Varies by app; some use a cloud service. | You decide. |
| Cost | Free daily pages; paid plans raise the allowance. | Licence or subscription. | Free with limits, or subscription. | Usually pay per page. |
When something else is the better choice
- You need a searchable PDF whose hidden text sits on each word. The PDF with text layer export keeps your original pages and places the OCR text invisibly over them, so search and copy work in any reader, but the text is placed per page, so highlights land approximately and the layer suits Latin script.
- The documents must never leave your device. Use software that runs locally.
- Your files are larger than 50 MB or you process thousands of pages a day.
Questions
Frequently asked questions
Is this online PDF text extractor really free?
Yes. You can try 1 page without an account, and a free account includes 50 pages a day with files up to 10 MB. Basic ($9.99 per month) allows 250 pages a day and adds image extraction; Pro ($29.99 per month) allows 1,000 pages a day. No card is needed to start. Create a free account when you want the full daily allowance.
How do I extract text from a scanned PDF?
Drop the PDF on the page and press Extract. A scanned PDF holds pictures of pages rather than real text, so the OCR model reads each page image and returns the words as Markdown. You can then check every page against its source, correct mistakes and download the result.
Which file types can I upload?
PDF, PNG, JPG and WebP. Each image counts as one page. HEIC, GIF, TIFF and BMP are not supported, so convert them to JPG or PNG first. Password-protected and damaged PDFs cannot be read.
Does image to text work on a photo or a screenshot?
Yes. Drop or paste (Ctrl/Cmd+V) a PNG, JPG or WebP file, or tap Scan with camera on a phone. Photograph the page straight on, in even light, with the text filling the frame, and the result will be much cleaner.
How accurate is the text extraction?
It depends on your document more than on the tool. Clear, upright, well-lit print reads best; blur, skew, low contrast and heavy compression cost accuracy, so we do not quote a single percentage. Read the result beside the source page, and double-check numbers, names and dates before you rely on them.
Can it read handwriting?
Often, when the writing is neat and well spaced, but handwriting is the hardest case for any OCR and errors are more likely than with print. Treat the output as a draft and review it against the source view.
Which languages does it support?
It reads many languages and detects the language itself, including pages that mix more than one. Latin-script languages such as English, Spanish, French, German, Italian, Portuguese and Dutch are the safest bet. For other scripts, test one page first: a guest run costs 1 page. The full list of what the model supports is in Mistral AI's documentation.
What happens to my files?
Your original is deleted from our server as soon as it has been read. The extracted text and images stay for up to 60 minutes so you can download them, then they are deleted automatically, and the Delete now button removes them sooner. Only you can open your results. Details are in the privacy policy.
Are my documents used to train AI models?
No. We do not use your documents for training, and our processor, Mistral AI, states that API data is not used to train its models. The privacy policy also explains the processor's own temporary retention.
How do I convert a PDF to Markdown, text or Word?
Extract the PDF, then open the Export menu. PDF to Markdown gives a .md file, PDF to text a .txt, and PDF to Word a .docx, PDF with text layer a searchable copy of your original pages, with .html and .json also on offer. All are built from the text on screen, including your edits and any redaction, and headings, lists and tables carry into Word. With redaction off, a ZIP package holds the original Markdown and any extracted images; with redaction on, the package is built from the redacted text and leaves the pictures out.
How do I get a table into Excel or Google Sheets?
Open the Tables tab, pick the table and choose Copy for Sheets/Excel, then paste into a cell. Download Excel saves it as a .xlsx workbook with numbers stored as numbers, and Download CSV saves the same table as a plain file. Check merged cells and totals afterwards, because complex layouts sometimes need tidying.
How are pages counted, and what if my PDF is longer than my allowance?
Every PDF page and every image counts as one page. Your browser counts pages before anything is sent and shows the total against what you have left today, and our server checks the count again. If a PDF is longer than your allowance, enter a range such as 1-3, 7 or choose Extract the first N pages. Only the pages you pick are uploaded and counted.
Can I hide personal details before I copy or share the text?
Yes. Turn on Redact to replace email addresses, phone numbers, card numbers, IBANs, US Social Security numbers, UK National Insurance numbers, IP addresses (IPv4 and IPv6) and dates of birth that carry a label such as Date of birth with labelled placeholders in the view, in copies, and in the Word, text, Markdown, HTML, JSON, CSV and ZIP package exports. While Redact is on the package holds the redacted Markdown and no pictures, because a picture cannot be redacted. Redaction works from patterns in your browser and does not find names or addresses, so read the text before you share it.
Can I use the extracted text commercially?
We claim no rights over the text you extract. Whether you may reuse it depends on your right to the source document, so check that before you publish or sell it.
Extract your first page
You can extract 1 page right now without an account. A free account raises that to 50 pages a day.
Keep going withAI HumanizerAI DetectorWriting AssistantSearch & CiteDecision LabAI Study Studio